publications
publications by categories in reversed chronological order. generated by jekyll-scholar.
conference papers
-
ICML
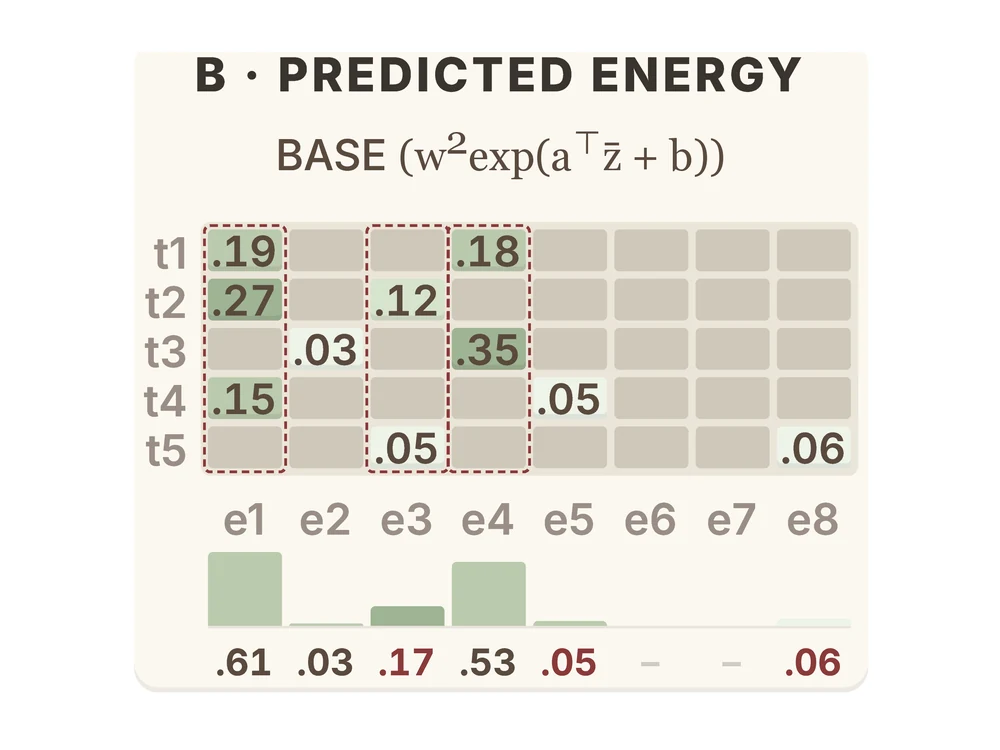
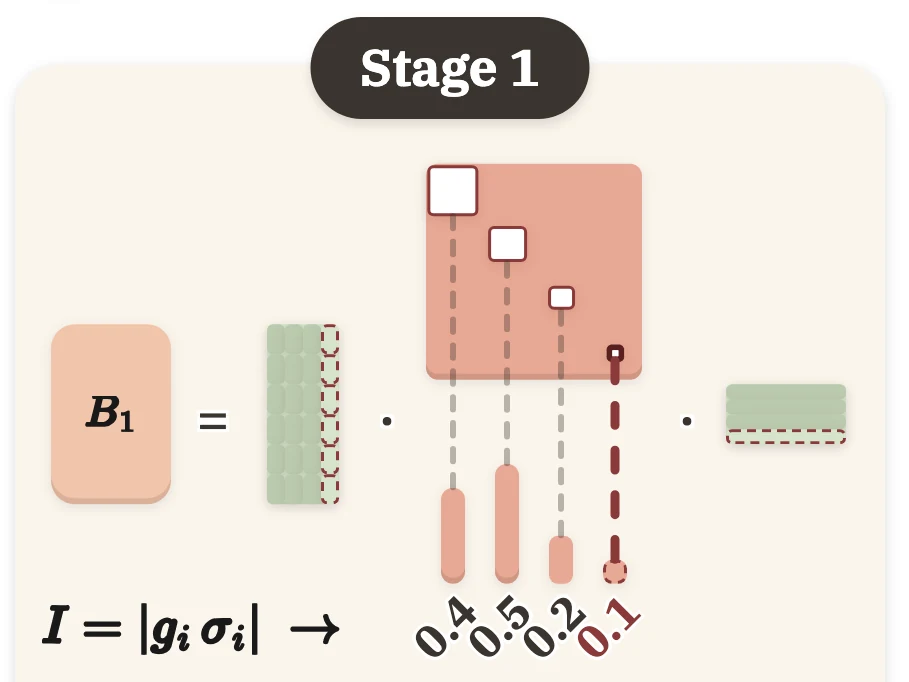
 Zero Sum SVD: Balancing Loss Sensitivity for Low Rank LLM CompressionIn International Conference on Machine Learning (ICML) 2026On-device demo: NVIDIA Jetson edge device
LLaMA-2-7B-Chat compressed with Zero-Sum SVD, keeping about 50% of the parameters in low-rank form with a different rank for each weight matrix and 8-bit quantization, running locally on an NVIDIA Jetson edge device.
Compared with the uncompressed model:
1.30×peak speedupat 1024 input tokens20–23%latency reductionend to end1.31×faster per tokentime per output token
preprints
-
arXiv
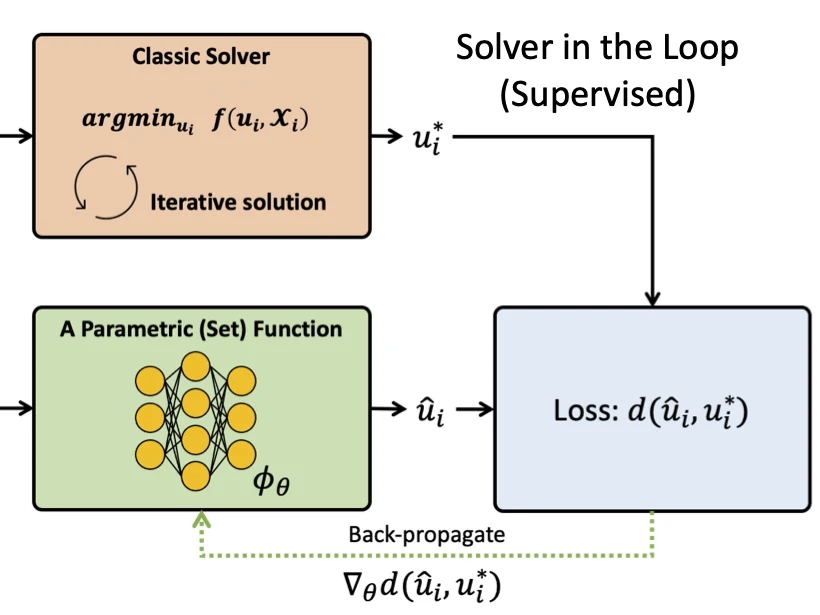 Teaching Networks to Solve Optimization ProblemsarXiv preprint arXiv:2202.04104 2022
-
arXiv
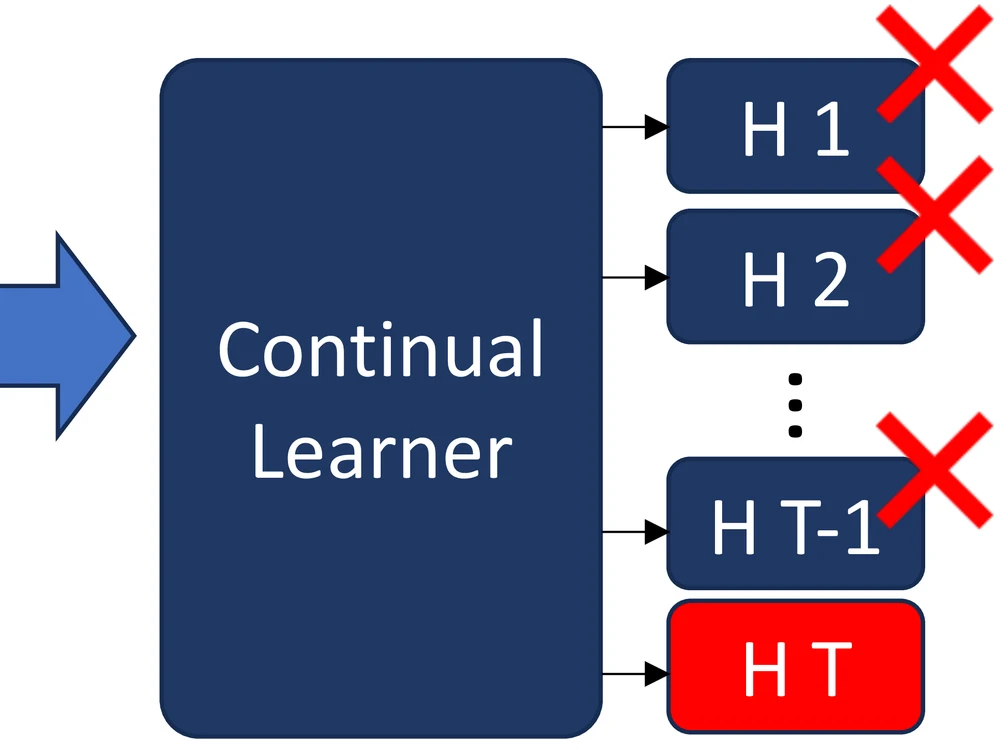
 Sparsity and Heterogeneous Dropout for Continual Learning in the Null Space of Neural ActivationsarXiv preprint arXiv:2203.06514 2022